Hey, I’m Joul 👋

I run three connected AI products: gen-image.com (B2C image & video generation), imference.com (multi-model inference API), and Runqy (open-source Go task queue powering both).

I’m more operator than engineer — I ship fast with AI assistance and share what that actually looks like here: GPU economics, spot-instance orchestration, moderation at scale, and running a profitable AI business without a big team.
A frame from a MiniMax H3 video generated on imference

Shipping MiniMax H3 three days after the weights dropped

MiniMax released the open weights for H3, their omni-modal video model, on August 3. By August 6 it was running in production on our own GPUs — text-to-video and image-to-video, with joint audio, served through gen-image, the imference API and Imference Desktop. We’re two developers working on this part-time. This post is about the unglamorous middle: what it actually takes to serve a frontier video model three days after the weights drop, when you don’t write custom kernels and don’t have a lab’s GPU budget. ...

August 7, 2026 Â· 5 min Â· Joul
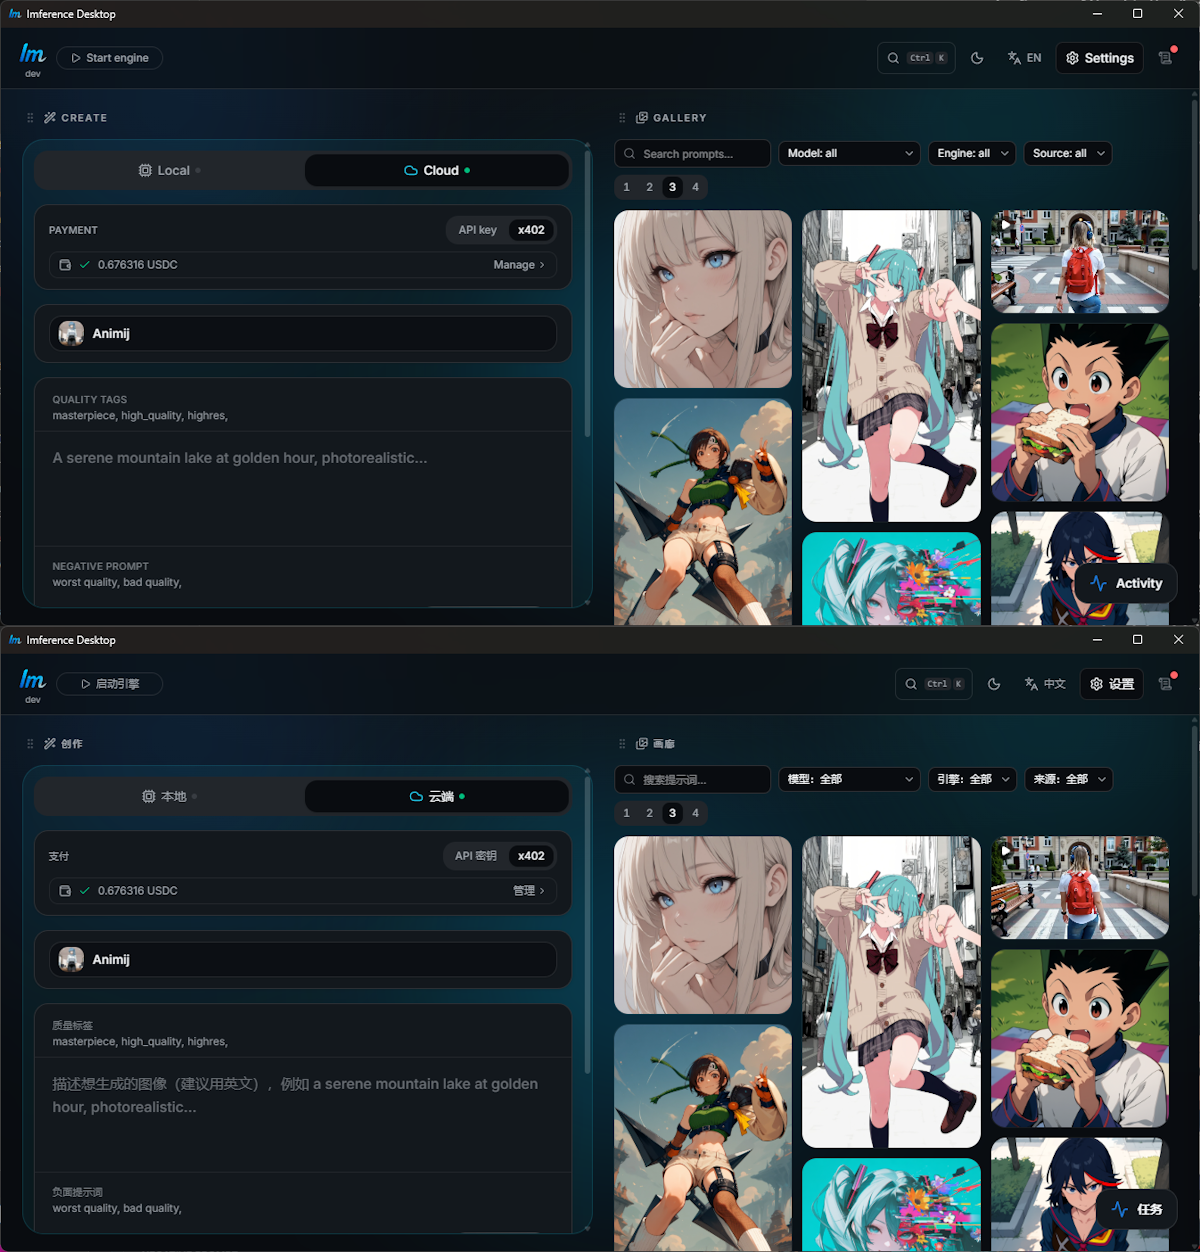
Imference Desktop main screen shown in English and in Chinese, stacked vertically

I translated my app into Chinese. I don't speak Chinese.

The translation itself took minutes. Verifying it found a bug that had been sitting in my app all along — in English too. Why bother While researching where local AI inference is actually popular, I kept running into the same answer: China. It makes sense — capable consumer GPUs, a strong self-hosting culture, a healthy distrust of cloud services. It’s also a market that’s structurally out of reach for Western cloud SaaS… but not for an open-source desktop app. Nothing to host, nothing to bill, nothing to block. ...

August 5, 2026 Â· 5 min Â· Joul